Two weeks ago "Jev" was nowhere. Now it is in every AI timeline, a TechCrunch headline calls it "thrilling developers", and someone on your team has asked whether you should be using it. You search what is Jev and Google hands you pages about the Japanese encephalitis virus.
This is the other Jev: Jev AI, the decision model TypeSafe AI released in early access on September 15, 2026. And the question most people are really asking is not what the letters mean. It is whether this is one more chatbot with a fresh logo, and whether claims like "can't hallucinate" and "hundreds of times cheaper" survive contact with real work.
We run jev-ai.org, a playground and API built on the Jev model, and we have been calling it through our own API since September 25, 2026. This guide is based on TypeSafe's own documentation, launch coverage from TechCrunch and SiliconANGLE, and six live requests we measured ourselves. By the end you will know what Jev AI is, how it differs from an LLM, what one call actually costs, and a one-line test for whether it belongs in your stack.
Last updated September 30, 2026. Jev is in early access and its prices and limits are still moving — the official pages linked below are the source of truth.
What Is Jev AI? The Short Answer
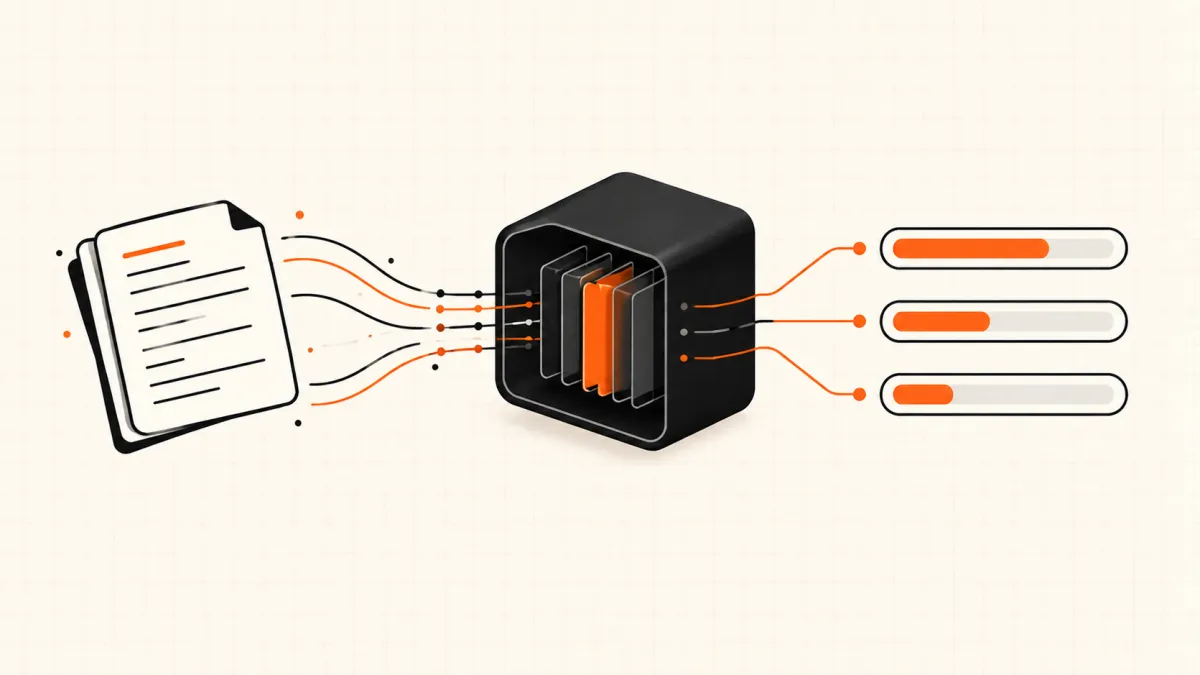
Jev AI is a model that answers typed questions about a piece of text and returns probabilities, instead of writing a response. You send it some state — a support ticket, a document, a JSON object — plus a set of questions whose answer shapes you declare up front. It sends back an answer to every question, the probability behind each option, and a confidence score. It never writes a sentence.
TypeSafe calls Jev "a frontier-intelligence function call: unstructured state in, typed probabilistic decisions out." Here is what that function looks like on paper, from the official models page:
| Jev at a glance | |
|---|---|
| Built by | TypeSafe AI, founded 2024 |
| Released | September 15, 2026, early access |
| Current version | jev-1.13.0; the alias jev-latest points to it today |
| Output | Typed answers + probabilities + confidence — no generated text |
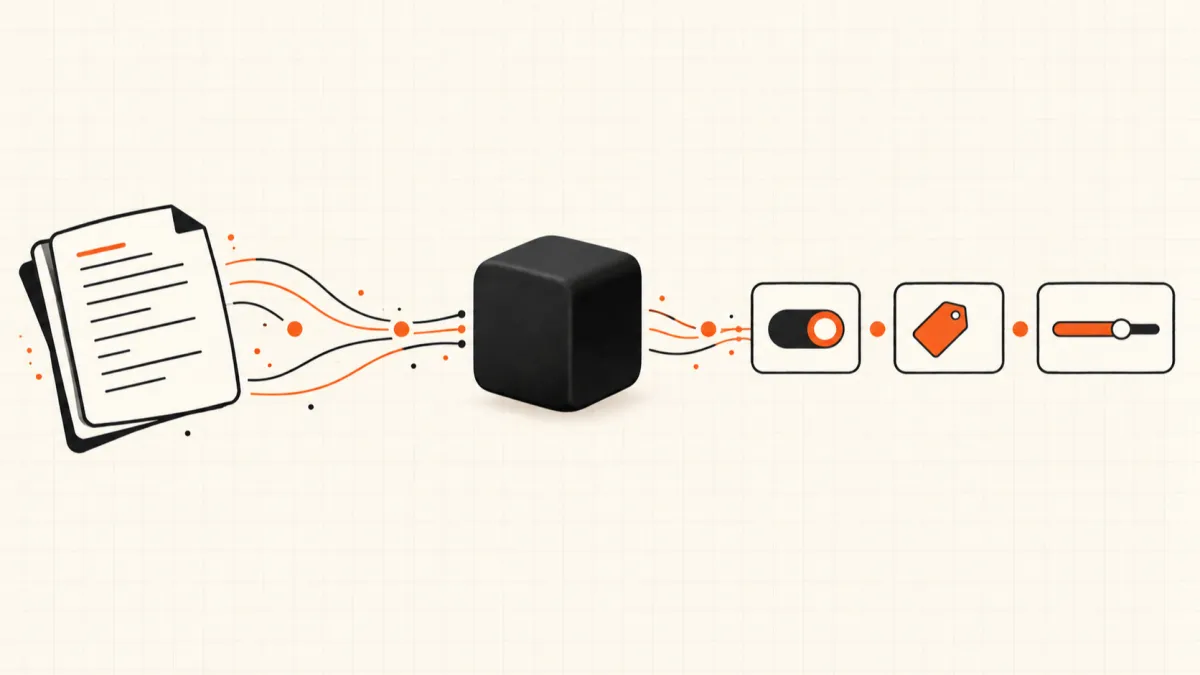
| Question types | choice, score and noul (a probability that a statement is true) |
| Input | Text only: a string, a JSON object or an array of text |
| Context | 64K tokens per request; 32K for the state plus the longest single question |
| Price | $0.042 per million input tokens; output tokens are free |
| Rate limits | 100,000 tokens/second and 40 requests/second (TypeSafe says these are adjusting) |
What Is Jev in AI Terms? A Model That Answers Instead of Writing
A large language model produces one token at a time, and everything else is downstream of that. Asking one for a decision means asking it to write a decision. That is why production code around LLM classification is mostly scaffolding: a prompt that begs for JSON, a parser, a schema validator, a retry loop, a fallback for the time it apologised instead, and a nagging doubt about what "confidence: high" in the output actually means.
Jev removes the writing step. The answer shape is part of the request, so there is nothing to parse afterwards — a malformed request fails with a 400 before the model runs, and a well-formed one cannot come back in the wrong shape. What you get instead of prose is the distribution: how much probability landed on each label or tier.
That distribution is what changes how you build. A choice split 0.52 / 0.48 is not a routing decision, it is a case to escalate — and you only know that because the model told you.
What "System One" means
TypeSafe describes Jev as the first System One model, a name borrowed from Daniel Kahneman's Thinking, Fast and Slow: System 1 is fast and intuitive, System 2 slow and deliberate. A chat model reasoning out loud is System 2. Jev is meant for the gut-check judgement software needs thousands of times a minute — the kind of call a knowledgeable person could make in a few seconds given the right context.
Is Jev an LLM?
No, although it understands text the way an LLM does. TechCrunch describes Jev as a transformer-based model that "is not a large language model": it has no completion, no streaming and no prompt to tune, and it does not write replies, code or explanations of its reasoning.
How is Jev trained?
TypeSafe trains Jev with a method it calls Reinforcement Learning for Calibrated Decisions (RLCD). Where chat models are tuned toward answers human raters prefer, RLCD optimises the probabilities against outcomes, so that higher confidence should mean higher accuracy. Almeida told TechCrunch the model is trained exclusively on synthetic data.
What TypeSafe has not published is the architecture, the weights or a technical paper. Outside observers suspect Jev is built on top of an open-weight LLM; the company has not confirmed that. Treat any detailed architecture diagram you see online as speculation.
How Jev AI Works: State In, Typed Decisions Out
Every Jev call has the same four-part shape:
- Prepare the state — the text or JSON the decision is about.
- Declare the questions — each with a type and, for
choiceandscore, the allowed answers. - Read the response — one typed answer per question, with probabilities.
- Let your code decide — branch, sort or escalate on those numbers.
The questions come in three types, and they can be mixed freely in one call. TypeSafe evaluates each question in parallel and in isolation against the same state, so adding a question barely changes the response time.
| Type | You declare | You get back | Example |
|---|---|---|---|
noul | Just the statement | One probability between 0 and 1 | "Does this message request a refund?" → 0.95 |
choice | An object mapping each label to a description | One of your labels, a probability for every label, and a confidence | billing / technical / account → billing |
score | An ordered array of tiers, lowest first | A decimal position on your scale, per-tier probabilities and a confidence | calm → very frustrated → 1.4 |
Two details catch almost everyone the first time:
- The criteria types are not interchangeable.
choicecriteria must be an object andscorecriteria must be an array; swap them and the request is a 400. - A score is a decimal on purpose. It is the expected value of the distribution, not the most likely tier. A 1.89 on a four-tier scale means most of the weight sits on tier 2 with some on tier 1 — which sorts correctly where a rounded integer would not. Store it as a float.
One request, three answers
A support ticket, three questions of three different types, one call to the jev-ai.org API. There is no system prompt, no few-shot block and no output parser.
POST /api/v1/systemone/
{
  "model": "jev-1.13",
  "state": "We were billed $49 twice on September 3. I opened ticket #4417 four days ago and have had no reply, and our books close Friday.",
  "questions": {
    "needs_human": {
      "type": "noul",
      "instructions": "Does this ticket need a human reply?"
    },
    "queue": {
      "type": "choice",
      "instructions": "Route this ticket to the team that owns the first reply.",
      "criteria": {
        "billing":   "Invoices, refunds, duplicate charges, plan changes.",
        "technical": "API errors, integrations, outages, SDKs.",
        "sales":     "Pre-purchase questions about plans or trials."
      }
    },
    "anger": {
      "type": "score",
      "instructions": "Rate the customer's frustration.",
      "criteria": ["Calm", "Mildly annoyed", "Frustrated", "Angry"]
    }
  }
}
The response has this shape (values are illustrative):
{
  "answers": {
    "needs_human": { "type": "noul", "noul": 0.89 },
    "queue": {
      "type": "choice",
      "choice": "billing",
      "probabilities": { "billing": 1, "technical": 0, "sales": 0 },
      "confidence": 1
    },
    "anger": {
      "type": "score",
      "score": 1.89,
      "probabilities": { "0": 0, "1": 0.11, "2": 0.89, "3": 0 },
      "confidence": 0.89
    }
  }
}
Every value there can go straight into an if, a queue name or a database column. The fastest way to get a feel for it is to change the ticket and watch the numbers move: the Jev AI playground loads nine ready-made scenarios you can edit without an account.
What Jev AI Costs and How Fast It Is: Six Real Calls
Every guide to Jev repeats TypeSafe's headline figures. None of the ones we read show a real bill, so here is ours. On September 25, 2026 we sent six production-shaped requests to jev-1.13 (build jev-1.13-20260917) through OpenRouter, each asking several typed questions of mixed types. The cost column is exactly what the API reported; latency is the full round trip from our machine, including TLS and transit.
| Workload | Input tokens | Cost of one call | Round trip |
|---|---|---|---|
| Answer grading | 795 | $0.00003339 | 969 ms |
| Intent routing | 539 | $0.00002264 | 318 ms |
| Citation check | 594 | $0.00002495 | 300 ms |
| Entity matching | 761 | $0.00003196 | 279 ms |
| Agent run review | 901 | $0.00003784 | 498 ms |
| Web page triage | 794 | $0.00003335 | 282 ms |
Read across the rows and three things stand out:
- A call costs two to four thousandths of a cent. A million calls of these workloads would come to roughly $23–$38 in model charges. Output tokens were counted in every response and billed at zero.
- The median round trip was about 310 ms, with one outlier near a second. That sits inside TypeSafe's published 70–500 ms end-to-end range once you add the network hop between us and their West Coast service.
- Price follows input size, not question count. The state is read once no matter how many questions ride along, so a fourth question is nearly free while a fourth request is not.
How to read the vendor's multipliers
TypeSafe's homepage claims Jev is up to 193.6× faster and 444.6× cheaper than frontier LLMs. The launch post is candid about where those numbers come from: four workflows written by its own model-capabilities team, scored against GPT-6 Astra and Fable 5.1 as the reference, with the company saying the gains are "on the higher end of real world gains". SiliconANGLE notes the figures have not been independently verified.
The strongest outside data point so far comes from a customer. A Vercel engineer told TechCrunch that replacing an LLM-based safety classifier with Jev returned results five to 18 times faster, with greater accuracy.
Rule of thumb: trust the per-token price, which you can check on your own invoice, and re-measure the speed multiplier on your own payloads before you plan around it.
What Is Jev AI Good For?
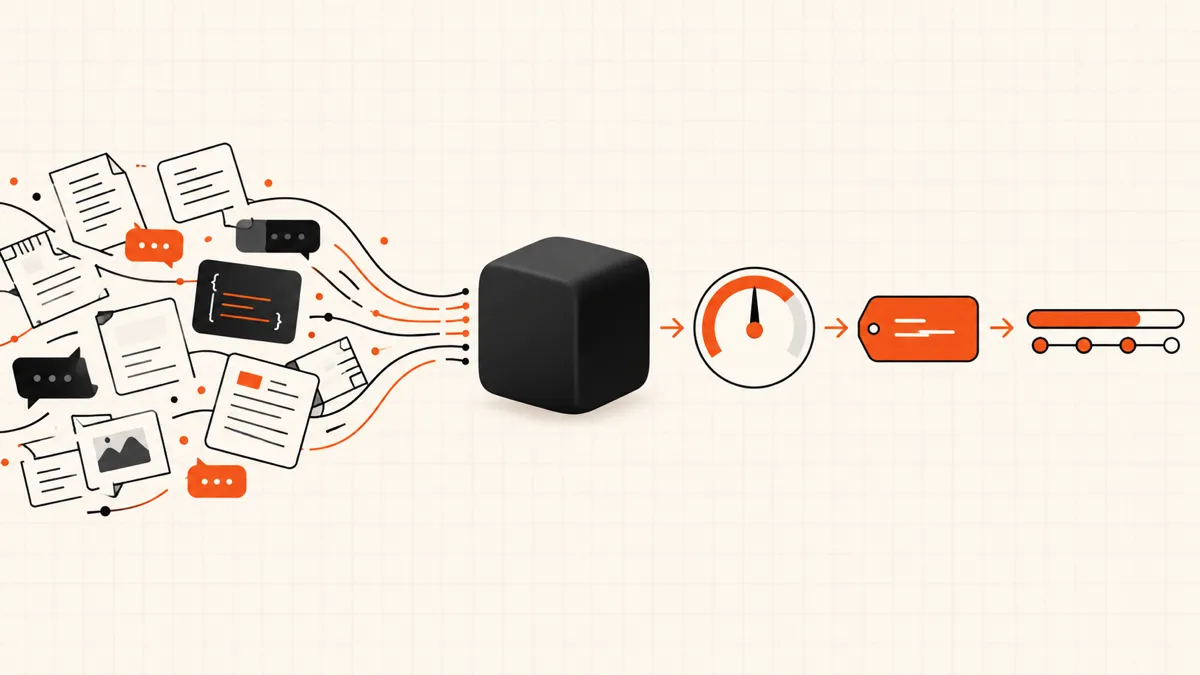
One question decides it: what does your code do with the answer? If it goes into an if, a database column, a queue name or a dashboard, Jev is the right shape of model. If a person is going to read it, it is not.
| Job | Jev? | Why |
|---|---|---|
| Routing a ticket or a prompt | ✅ Strong fit | A choice with probabilities is exactly a routing decision — see the LLM router |
| Grading answers or agent runs | ✅ Strong fit | score gives a sortable number instead of a paragraph of critique |
| Checking a citation against its source | ✅ Strong fit | A noul "is this supported?" is a guardrail you can threshold |
| Screening pages before they enter a context window | ✅ Strong fit | Fast enough to run on every fetched page |
| Pulling a few known fields out of text | ⚠️ Works | Only when you know the fields in advance |
| Summaries, drafts, translation, code, chat | ❌ Wrong tool | Jev cannot produce text; use a generative model |
| Open-ended analysis | ❌ Wrong tool | Every question has to be declared up front |
The pattern that works best, according to TypeSafe's docs, is to split one big judgement into several atomic questions and combine the answers in code. "Rate this startup pitch" becomes separate questions about market size, feasibility and differentiation — and when priorities change, you change a weight in your code rather than rewriting a prompt. Each pattern above has a runnable example and a measured cost on our Jev AI use cases page.
Limits to Know Before You Build
- Text only. Images, audio and video are not supported yet; turn them into text or structured fields first.
- No fine-tuning. The same weights serve every account. You adapt Jev through the state, the instructions and the criteria you send, not through training.
- Aliases move.
jev-latestfollows new releases, so answers behind it can change without any change on your side. If you tune confidence thresholds, pin the version and move on your own schedule. - Calibration is a group property. TypeSafe's docs are explicit that calibration is measured across many predictions and does not guarantee any single answer is right. Keep a human or a reasoning model on the low-confidence tail.
- Early-access limits. Rate limits are adjusting while TypeSafe adds capacity. TypeSafe dropped the launch waitlist on September 20, 2026 and, after a short pause, reopened sign-ups to everyone on September 27 — what changed and how to get access.
Who Makes Jev? TypeSafe AI and Diogo Almeida
Jev is built by TypeSafe AI, founded in 2024 by chief executive Diogo Almeida with co-founders Erik Gafni and Sasha Sheng. Almeida spent years at OpenAI on the research behind ChatGPT — RLHF, InstructGPT, ChatGPT and GPT-4 — and has described leaving because chat models, for all their ability, were not useful for automation. TypeSafe worked in stealth for about two years and launched Jev alongside a $40 million seed round led by DCVC.
The name is not an acronym. Jev is named after William Stanley Jevons, the 19th-century economist behind the Jevons paradox: when a resource gets cheaper to use, people end up using far more of it. Almeida's bet is that cheap machine judgement will end up inside ordinary software everywhere.
jev-ai.org gives access to the Jev model and adds a playground, a batch workbench and an API of its own.
How to Try Jev AI in Five Minutes
The cheapest way to find out whether Jev fits is to run it on one decision you already make today.
- Pick a scenario in the Jev AI playground — routing, grading, citation checks and six more are preloaded.
- Swap in your own text. Paste a real ticket, answer or document into the state, and edit the questions. None of this needs an account.
- Run it. Sign in for five free credits, with no card and no waitlist, and read the probabilities that come back. If they split close to 50/50 on cases a person finds easy, rewrite the question to be narrower before judging the model.
- Ship the same body. When the answers look right, send the identical request through the Jev AI API, or upload a CSV to batch processing to score thousands of rows at once.
FAQ
What does JEV stand for?
In AI, nothing — Jev is a name, taken from the economist William Stanley Jevons. In medicine, JEV stands for Japanese encephalitis virus, which is why a plain search for "what is jev" mixes the two.
Is Jev AI free?
Editing the playground scenarios is free and needs no account, and new accounts on jev-ai.org get five free credits to run them. After that you pay for input tokens only; TypeSafe's list price is $0.042 per million, with output free. Plans are on the pricing page.
Is Jev made by OpenAI?
No. TypeSafe AI is an independent company. Its founder previously worked at OpenAI, which is where the association comes from.
Can I download Jev AI or run it locally?
No. TypeSafe has not released weights, so there is no download and no Ollama build. Jev runs as a hosted model you call over an API. If you need something self-hosted, see our comparison of Jev and the OpenJev projects.
How is Jev different from ChatGPT?
ChatGPT writes text for people to read. Jev returns decisions for software to act on. If you have ever asked a chat model to "reply only with JSON", Jev is the model built for that job — our Jev vs LLM structured output comparison goes through the trade-off in detail.
The Bottom Line
Jev AI is not a better chatbot; it is a different kind of model, and it earns its keep in the parts of your system where a decision gets made and nobody reads the output.
- It answers declared
noul,choiceandscorequestions with probabilities, and never writes text. - In our six real calls, one decision cost two to four thousandths of a cent and usually came back in about a third of a second.
- It fits routing, grading, guardrails and triage; it does not fit anything a person needs to read.
- It is early: text only, no fine-tuning, and limits that are still changing.
Start with one decision you already pay an LLM to make. Open the Jev AI playground, paste in a real example, and compare the answer — and what it cost — with what you get today.
Sources
- Introducing System One Models & Jev — TypeSafe AI — Launch date, RLCD, list price, speed range and the caveats on the vendor's benchmark multipliers.
- Models — TypeSafe AI docs — Version, aliases, context budget, rate limits, input types and the no-fine-tuning policy.
- System One — TypeSafe AI docs — What a System One model is and the three question types.
- A new kind of AI model from a ChatGPT inventor is thrilling developers — TechCrunch — Founder background, synthetic-data training, the unpublished architecture and the Vercel result.
- TypeSafe AI exits stealth with $40M — SiliconANGLE — Funding, co-founders and early-access availability.
Prices, rate limits and model versions are as published on September 30, 2026 and are likely to change during early access. The six measured calls are our own and reflect our payloads and network location.