"It's not an LLM." "It can't hallucinate." "It's two hundred times faster." If you have read anything about Jev this month, you have read those three claims — and almost nothing about the machinery that is supposed to make them true. Ask a search engine how does Jev work and it may even start suggesting pages about the Japanese encephalitis virus, which is also abbreviated JEV.
This guide is about the other Jev: the decision model TypeSafe AI released on September 15, 2026. If you are new to it, start with what Jev AI is and come back; here we go one level down. You will learn what happens between the request and the response, how RLCD training differs from the RLHF behind chat models, why asking more questions barely changes the price, what calibration does and does not promise — and, just as important, which parts of the model TypeSafe has never published.
We run jev-ai.org, a playground and API built on Jev. Everything below comes from TypeSafe's documentation (its AI primer, Models, Confidence and "jaggedness" pages), its launch post, launch coverage from TechCrunch, and our own measured calls. Where something is speculation, we label it as speculation.
Last updated September 30, 2026, for jev-1.13. TypeSafe says many of the model's current limits will change in later versions.
How Does Jev Work? The Short Answer
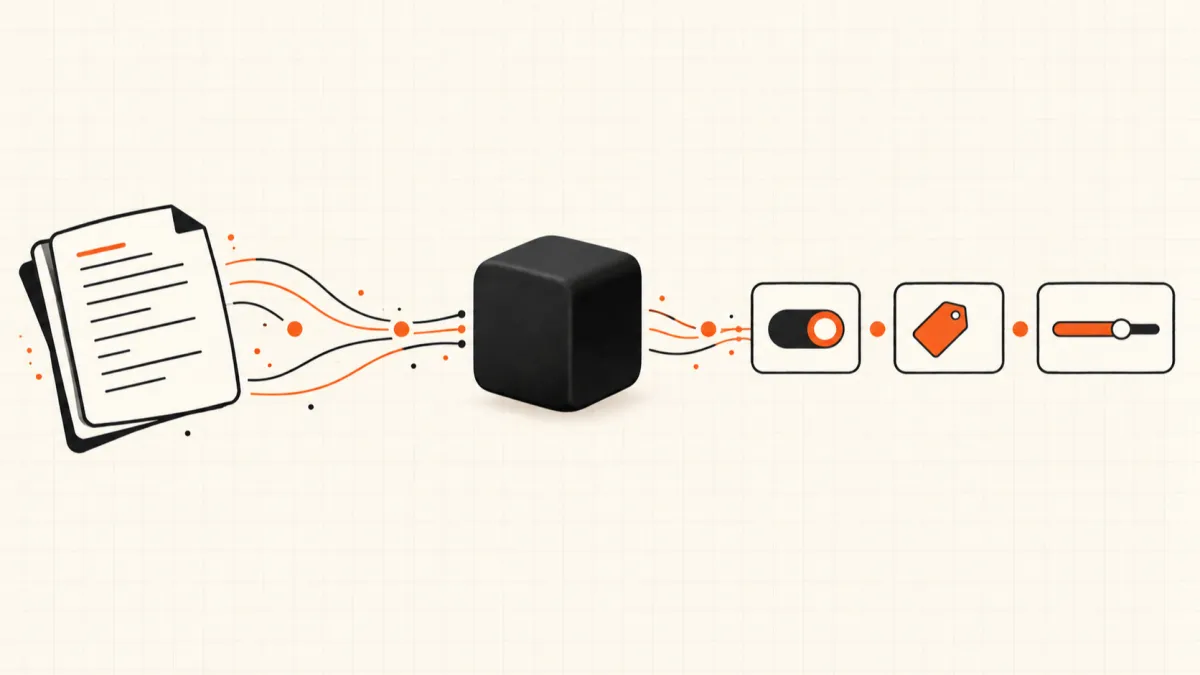
Jev reads a piece of text once, answers every typed question you ask about it in parallel, and returns a probability for each allowed answer instead of generating words. You declare the possible answers up front — a set of labels, an ordered scale, or a yes/no statement — so the model's only job is to decide how much probability each one deserves. TypeSafe trains it with Reinforcement Learning for Calibrated Decisions (RLCD), which rewards those probabilities for matching real outcomes, so a 0.8 should be right about 80% of the time across many predictions. Your code then acts on the numbers: automate the confident cases, escalate the rest.
That is the whole contract. Everything else in this article is detail on one of those four steps.
The Pipeline, Step by Step
Every Jev call has the same shape, whether it comes from TypeSafe's own API or from ours:
| Step | What goes in | What Jev does | What comes out |
|---|---|---|---|
| 1. State | A string, a JSON object or an array of text | Reads it once | — |
| 2. Questions | One or more typed questions, each noul, choice or score | Fixes the answer space before any computation | — |
| 3. Evaluation | — | Evaluates every question against the same state, in parallel and in isolation | A probability distribution per question |
| 4. Answer | — | Summarises each distribution | A probability (noul), a label plus distribution and confidence (choice), or a decimal position plus distribution and confidence (score) |
| 5. Decision | — | Nothing — this part is yours | Your code branches, sorts or escalates |
The three question types, as TypeSafe's System One docs define them:
noulasks whether a statement is true and returns one probability between 0 and 1.choicepicks one option from a set you define, with a probability for every option.scoreplaces the state on an ordered scale you define. The answer is the expected position under the distribution, so a 1.89 on a four-tier scale means "mostly tier 2, some tier 1" — a number you can sort and threshold on.
Notice what is missing: there is no prompt template, no system message, no temperature and no output parser. The answer shape is part of the request, so a malformed request fails before the model runs and a well-formed one cannot come back in the wrong shape.
Is Jev an LLM?
It depends on which definition of "LLM" you use — which is exactly why the question keeps coming up.
- TechCrunch describes Jev as a new transformer-based model that "is not a large language model".
- TypeSafe's own FAQ says Jev "is neither small nor an LLM": it understands language but does not generate free-form text or act as a chatbot.
- InfoWorld, covering the same launch, called it "a new LLM".
The disagreement is about vocabulary, not behaviour. Like an LLM, Jev understands natural language — TypeSafe's docs say so directly. Unlike an LLM, it never produces text. It has no completion, no streaming and no chat turn, and it will not write a reply, code, or an explanation of its reasoning.
For practical purposes, the useful definition is the output contract. If you need words, Jev is the wrong model. If you need a decision your software can act on, it is built for exactly that — which is why people searching for a "Jev LLM" usually end up comparing it with LLM structured output rather than with other chat models.
How Is Jev Trained? RLCD in Plain English
TypeSafe's AI primer frames Jev's training as a third way of adapting a pretrained model, alongside the two that produced today's chat and reasoning models:
| Post-training method | What it optimises for | What it produced |
|---|---|---|
| RLHF — reinforcement learning from human feedback | Responses human raters prefer | Chat models such as InstructGPT and ChatGPT |
| RLVR — reinforcement learning with verifiable rewards | Outputs a program can check, like a correct maths answer | Reasoning models: strong, but slower and more expensive |
| RLCD — reinforcement learning for calibrated decisions | Probabilities that match real outcomes | Jev |
The choice of RLHF as the foil is personal. TypeSafe's co-founder and CEO, Diogo Almeida, is credited by the company with co-inventing RLHF at OpenAI. His argument is that RLHF optimises the wrong thing for automation: a model trained to produce what people prefer is rewarded for sounding confident, which encourages sycophancy and confident-sounding mistakes. The primer also describes mode dropping — preference training narrows the range of outputs a model considers likely, which is the opposite of what you want from a model whose job is to report honest uncertainty.
RLCD sets a different contract, per the primer:
- The model does not generate text.
- It returns decisions and probabilities.
- Higher probability should mean a greater chance of being right.
What "calibrated" means, precisely. Across many predictions from a well-calibrated model, outcomes given a probability of 0.2 happen about 20% of the time, and outcomes given 0.8 happen about 80% of the time. TypeSafe has not published RLCD's reward function. The general idea behind any calibration objective, though, is simple: a confident wrong answer must cost far more than a hesitant wrong answer, so the model learns that saying 0.95 is only worth it when it is right almost every time. That is the property that makes a probability usable as a threshold.
Where the training data comes from. TechCrunch reports that Jev is trained exclusively on synthetic data, and TypeSafe's launch post says the company makes all of its training data itself. Its Models page adds that Jev is not trained on customer requests or responses, and that it is not fine-tuned or LoRA-adapted per customer: the same weights serve every account. You adapt Jev through what you send — the state, the instructions and the criteria — not through training.
Why Jev Is Fast and Cheap: Parallel, Not Autoregressive
A chat model writes one token at a time, each conditioned on the last. Even when you only want the word "billing", the model still generates it token by token, and every extra field in a JSON answer means more sequential steps.
TypeSafe says it built "a new model architecture, parallel sampler for maximum efficiency" for Jev, and its launch post describes the key difference as Jev outputting "all probabilities in parallel instead of autoregressively generating by token". The company's FAQ puts it as replacing sequential generation with parallel computation — and compares the jump to the one transformers made over recurrent networks.
Three consequences follow, and all three show up on the invoice:
- Output is free. TypeSafe bills input tokens only, at $0.042 per million, because there is no long generated answer to pay for.
- The state is read once. Every question is evaluated against the same ingested state, so a fourth question adds only its own few tokens. TypeSafe's parallel-questions cookbook ran a 13-question briefing over one article and found that batching the questions into one call was 12.2× cheaper and 10× faster than sending them separately, with no change in the answers.
- Latency is short and flat. TypeSafe publishes an end-to-end range of 70 to 500 ms.
Our own numbers line up. On September 25, 2026 we sent six production-shaped, multi-question requests to jev-1.13 (build jev-1.13-20260917). Input sizes ran from 539 to 901 tokens, each call cost between $0.000023 and $0.000038, and the median round trip from our machine was about 310 ms, with one outlier near a second. The per-call breakdown is in our what-is-Jev test.
Parallel and Isolated: What That Means for Your Questions
"Parallel" gets the attention, but "isolated" is the half that changes how you write requests. TypeSafe's docs are explicit: every question sees the same state and is evaluated independently, and one question's answer never becomes hidden context for another.
That has three practical effects.
1. You cannot chain inside a call. If the right way to ask question B depends on the answer to question A, that is two requests: ask A, let your code read the answer, then build B. Inside one request, each question is on its own.
2. You can ask speculatively. Because unused answers cost almost nothing, TypeSafe recommends a "speculative fan-out": ask everything your code might need — severity and refund intent and language — and ignore the answers that turn out to be irrelevant for this input.
3. The model does not enforce logic between questions. This is the non-obvious one, and TypeSafe documents it with its own numbers. Asked on the same ticket whether the customer wants a refund, and separately whether they want something other than a refund, jev-1.13 returned 0.72 and 0.47 — which add up to 1.19, not 1. And the same refund question asked once as a noul and once as a yes/no choice returned 0.22 and 0.01 respectively. Each answer is internally sensible; together they are not a coherent probability model.
Rule of thumb: ask each decision exactly one way, keep any arithmetic between answers in your code, and never reuse a threshold you tuned on a noul for a choice.
Calibration and Confidence: What the Numbers Promise
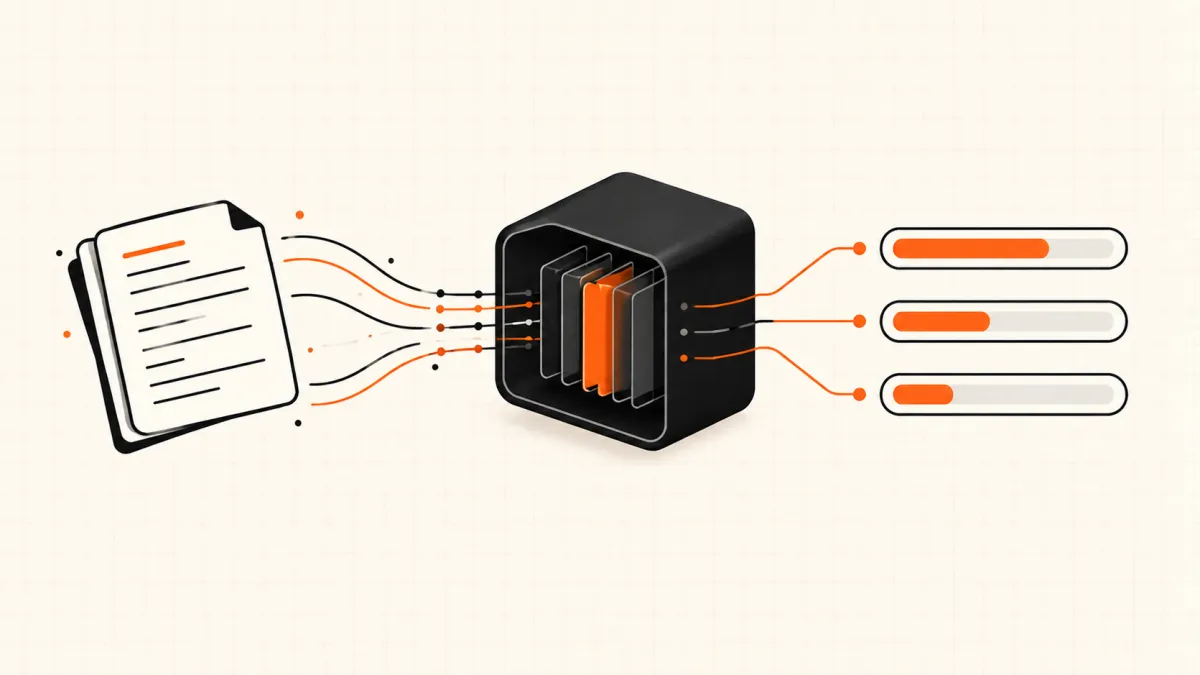
Every choice and score answer carries two things: the full probabilities and a single confidence between 0 and 1. Confidence is derived from the shape of the distribution — all the weight on one option gives 1.0, an even spread gives 0. For a three-option choice, TypeSafe's docs illustrate it as (3 × top probability − 1) / 2, so a 0.9 / 0.06 / 0.04 split scores 0.85 while a 0.40 / 0.33 / 0.27 split scores only 0.10.
A noul has no separate confidence field and does not need one: its distance from 0.5 is the confidence. That is why a single threshold at 0.5 throws away the most useful part of the answer. A two-sided rule — act above 0.9, ignore below 0.1, send the middle to a person — keeps it.
TypeSafe's Confidence guide suggests three bands:
| Confidence | What your code should do |
|---|---|
| High | Act automatically |
| Medium | Proceed with care: confirm with the user, flag for review, or gather more context |
| Low | Do not act: route to a person, ask for clarification, or fall back to a reasoning model |
The boundaries depend on the stakes. A read-only action can run at a lower threshold than an irreversible one, and the docs' own example gates a funds transfer at 0.9 while letting a balance check through at anything above 0.5.
Two warnings from TypeSafe itself are worth keeping in view. Calibration is measured across groups of predictions; it does not guarantee any single answer is right. And a valid shape is not a correct answer: in the company's words, if you give Jev a list of categories it cannot invent one outside that list — but it can still choose the wrong one.
The Context Budget
TypeSafe's Models page gives jev-1.13 two limits that work together:
- 64K tokens per request for the state plus all questions combined.
- 32K tokens for the state plus the single longest question.
Because the state is ingested once and every question is evaluated against it, the realistic ceiling on how much you can ask is far higher than the ceiling on how much you can show. Input is text only — strings, JSON objects or arrays of text — and English is the primary training language; TypeSafe says other languages, CJK scripts included, work but less well.
The bigger practical limit is not the token count but relevance. TypeSafe warns that accuracy falls as the state fills up with material unrelated to the decision, and it calls this context rot. Filter and retrieve in code first, send only the fields the question needs, and your answers get sharper and cheaper. (The jev-ai.org endpoint has its own per-call caps, listed in our rate limits and quotas.)
What Jev Gets Wrong, by Design
TypeSafe maintains a page it calls "Jev 1.13 jaggedness", listing the failure modes it already knows about. Condensed:
| Failure mode | Why it happens | What to do instead |
|---|---|---|
| Literal reading | It answers the question you wrote, not the one you meant | State the exact condition; put boundary cases in the criteria |
| Counting and arithmetic | It recognises the shape of an answer rather than tallying | Count and calculate in code; ask one question per item |
| Comparing dates | It reads dates as text, not ordered quantities | Extract the parts with choice questions; compare in code |
| Indirection | Double negatives and multi-hop questions cost accuracy | Ask directly; point to the relevant part of the state |
| Large irrelevant state | Unrelated detail acts as a distractor | Filter first; use a noul to test relevance |
| Adversarial content | Text written to steer the model can move the answer | Be explicit in the criteria; test edge cases before launch |
| Contradictory wording | Instructions and criteria pulling different ways confuse it | Write both in plain, aligned language |
| Generation | It is not trained to write text | Use a generative model; let Jev pick among extracted candidates |
Read that table as a job description. Jev is built for fast, common-sense judgements — classify, route, score, verify — and TypeSafe's own FAQ says tasks needing extended reasoning, such as complex maths or chess-like planning, belong to large reasoning models.
What TypeSafe Has Published — and What It Hasn't
Most explanations of Jev online either repeat the launch post or fill the gaps with confident diagrams. Here is where the line actually sits as of September 30, 2026:
| Published by TypeSafe | Not published |
|---|---|
| The output contract: three question types, typed answers, probabilities, confidence | The architecture — beyond "a new model architecture" and a "parallel sampler" |
| The training method's name and objective (RLCD, calibrated probabilities) | RLCD's reward function and training recipe |
| That training data is synthetic and made in-house | What that data consists of |
| Price, context budget, rate limits, input types | Parameter count and the base model, if any |
| Known failure modes, in detail | A technical paper or model card |
| Its own workflow evaluations, with stated biases | Scores on public benchmarks — deliberately, per the launch post |
| That Jev is not fine-tuned per customer | The weights, which have not been released |
TechCrunch reports that outside observers suspect Jev is built on top of an open-weight LLM, and that Almeida is "tight-lipped" about the architecture. That is plausible; it is also unconfirmed. Treat any detailed architecture diagram you see — encoder heads, adapted decoders, specific base models — as someone's hypothesis, not a description.
One more distinction from TypeSafe's FAQ is worth knowing: Jev is designed for consistency rather than strict determinism. The company defines consistency as making similar decisions when the meaning stays similar, even if the wording changes — a property you can test on your own data.
The fastest way to build intuition for all of this is to watch the numbers move. Open the Jev AI playground, load a scenario, change one sentence of the state and run it again: you will see the distribution shift, the confidence drop, and exactly where your question needs to be narrower.
Where This Leaves You
Understanding the mechanism turns into four design rules:
- Decompose. Split every broad judgement into narrow questions and combine them in code, where you control the weights.
- Ask everything at once. Same state, one request, as many questions as you need; they run in parallel and cost little.
- Threshold on confidence, not just the answer. Decide in code what happens at high, medium and low confidence, and scale the bar with the stakes.
- Pin the version you tuned on.
jev-latestmoves when TypeSafe ships; logmodel_versionon every answer and change versions on your own schedule.
If you want the company context behind these choices, our profile of TypeSafe AI covers the founders and what else they ship. And if you are weighing Jev against the GPT model you already use, see how Jev compares with OpenAI's models.
FAQ
How does Jev work compared with BERT?
A BERT-style classifier is an encoder you fine-tune for one task: its labels are fixed at training time, and adding a label means retraining. Jev takes its labels, scale or statement in each request as plain-language descriptions, with no training on your side, and returns probabilities trained to be calibrated. A fine-tuned classifier can still be cheaper and more accurate on a stable, well-labelled task — our Jev vs fine-tuned classifier comparison walks through when. TypeSafe has not said whether Jev's own architecture resembles an encoder.
Does Jev learn from my data?
No. TypeSafe says Jev is not trained on customer requests or responses and is not fine-tuned per account.
Is Jev deterministic?
TypeSafe designs for consistency — similar answers for similar meaning — rather than promising identical output for identical input. If you need reproducibility over time, pin a version such as jev-1.13 instead of the jev-latest alias.
Can Jev hallucinate?
It cannot return an answer outside the options you declare, so it cannot invent a category or a malformed value. It can still choose the wrong option, which is what the probabilities and confidence are for.
How is Jev different from JSON mode or structured outputs?
Structured outputs make a text-generating model's answer fit a schema. Jev is trained for the decision itself and returns a calibrated probability for every allowed answer, which a schema alone does not give you.
Will TypeSafe publish Jev's architecture?
TypeSafe has not published an architecture paper or announced a date for one. Its launch post describes only a new architecture, a parallel sampler and the RLCD training method.
The Bottom Line
Jev works by giving up the one thing every chat model is built around — generating text — and spending that budget on something software can use directly: a calibrated probability for every answer you allow.
- It reads the state once and evaluates each typed question in parallel and in isolation.
- RLCD trains its probabilities to match outcomes, so confidence becomes a threshold you can act on.
- Parallel evaluation is why output is free, extra questions are nearly free, and latency stays short.
- Its weaknesses are documented: literal reading, arithmetic, dates, indirection, noisy state and generation.
- Its architecture, parameter count, base model and training data remain unpublished.
The mechanism is easiest to trust once you have seen it on your own inputs. Build a request in the playground, then send the same body through the Jev AI API when the answers look right.
Sources
- AI primer — TypeSafe AI docs — RLHF, RLVR and RLCD, the definition of calibration, mode dropping.
- Models — TypeSafe AI docs — Context budget, input types, language support, aliases, no per-customer fine-tuning, data handling.
- Confidence — TypeSafe AI docs — How confidence is derived from probabilities, the three action bands and risk-scaled thresholds.
- Introducing System One Models & Jev — TypeSafe AI — New architecture and parallel sampler, pricing, latency range, in-house data, no public benchmarks.
- A new kind of AI model from a ChatGPT inventor is thrilling developers — TechCrunch — Transformer-based but not an LLM, synthetic-data training, the unpublished architecture.
Model behaviour, limits and failure modes are as documented for jev-1.13 on September 30, 2026; TypeSafe updates its docs without notice. The six measured calls are our own and reflect our payloads and network location.